VividAnimator: An End-to-End Audio and Pose-driven Half-Body Human Animation Framework
11月 10, 2025·, ·
1 分钟阅读时长
Donglin Huang
Equal contribution
,Yongyuan Li
Equal contribution
,Tianhang Liu
Equal contribution
,Junming Huang
Xiaoda Yang
Chi Wang 王驰
Corresponding author
,Weiwei Xu
摘要
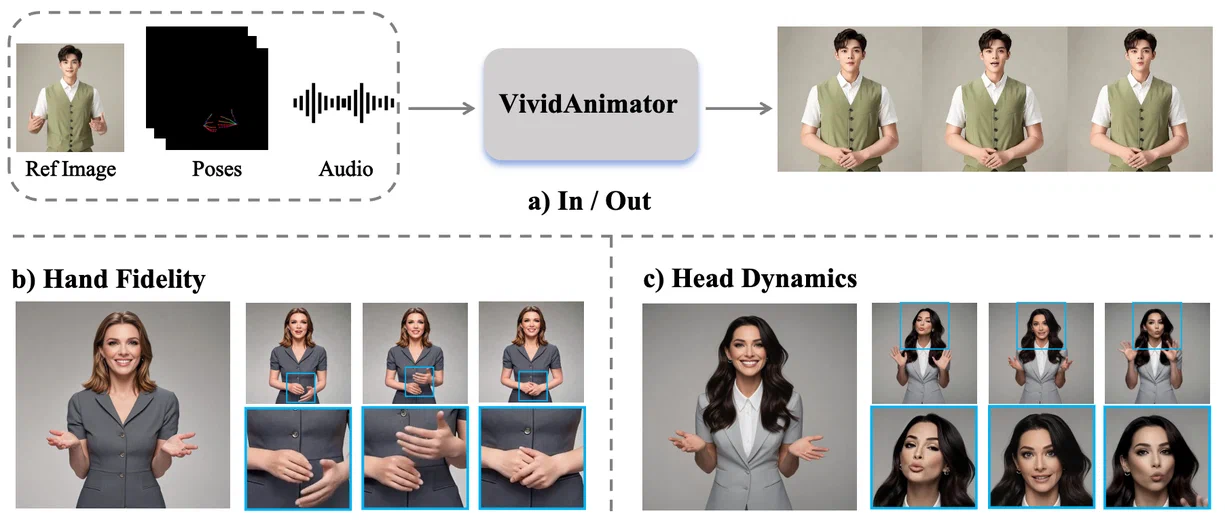
Existing for audio- and pose-driven human animation methods often struggle with stiff head movements and blurry hands, primarily due to the weak correlation between audio and head movements and the structural complexity of hands. To address these issues, we propose extbf{VividAnimator}, an end-to-end framework for generating high-quality, half-body human animations driven by audio and sparse hand pose conditions. Our framework introduces three key innovations. First, to overcome the instability and high cost of online codebook training, we pre-train a Hand Clarity Codebook (HCC) that encodes rich, high-fidelity hand texture priors, significantly mitigating hand degradation. Second, we design a Dual-Stream Audio-Aware Module (DSAA) to model lip synchronization and natural head pose dynamics separately while enabling interaction. Third, we introduce a Pose Calibration Trick (PCT) that refines and aligns pose conditions by relaxing rigid constraints, ensuring smooth and natural gesture transitions. Extensive experiments demonstrate that Vivid Animator achieves state-of-the-art performance, producing videos with superior hand detail, gesture realism, and identity consistency, validated by both quantitative metrics and qualitative evaluations.
类型
出版物
In The IEEE/CVF Winter Conference on Applications of Computer Vision
注意
Click the Cite button above to demo the feature to enable visitors to import publication metadata into their reference management software.
